Key takeaways
- Weak supervision can simplify data labelling tasks by leveraging existing knowledge resources.
- The challenge of data labelling is significant for organisations adopting machine learning technologies.
- High-quality labels require structured processes, including collecting labels and training experts.
- Google's Snorkel Drybell framework enhances label generation through generative modelling techniques.
 If a model is tasked with identifying dogs from a random collection, then one can use named-entity recognition to label any content that does not contain the names of dog breeds. Existing knowledge resources can be combined with such simplistic logic to label training data for using it in a new model.
This labelling function returns ‘None’ more often, which leads to only a few parts of data getting labelled.
Any organisation that looks towards machine learning will have to deal with the challenges that come with data labelling. The need for hand-labelled training datasets becomes obvious right at the beginning of the pipeline.
Data labelling requires the following:
- Collecting labels
- Developing label instructions
- Training subject matter experts to carry those instructions
- Deal with failing training datasets with evolving applications
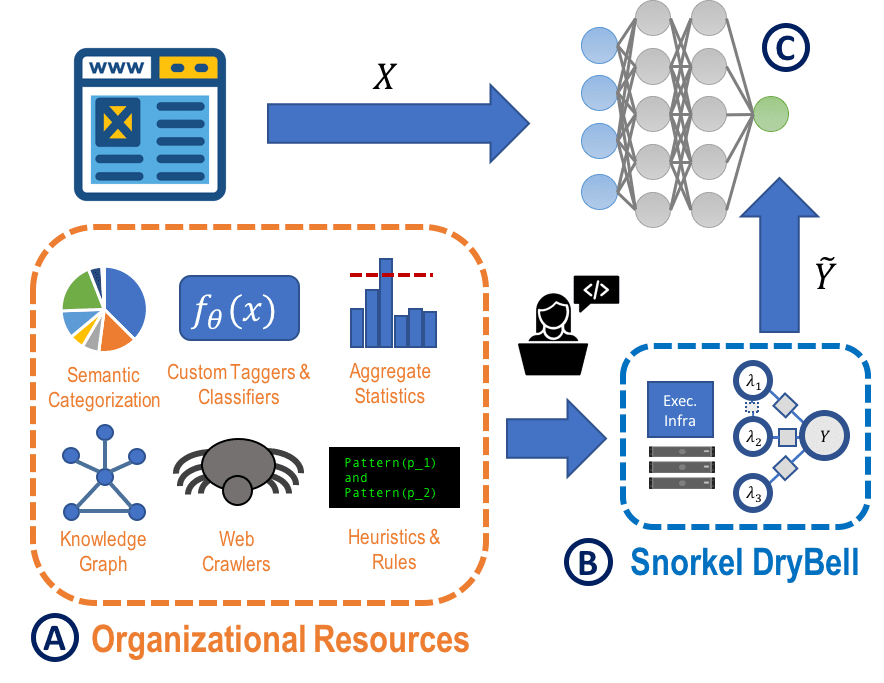
- Heuristics and rules
- Taggers and classifiers
- Aggregate statistics
- Entity graphs
Key Findings
- Users can write labelling functions over on unservable feature set and then use the output to train model over different servable feature set.
- This feature boosts performance by an average of 52% on the benchmark datasets.
- Efficient and inexpensive deployment of models.
- A new kind of transfer learning- transferring domain knowledge between different feature sets.