Key takeaways
- Advancements in AI now allow machines to learn and adapt in ways previously thought possible only in science fiction.
- Current AI systems have a limited understanding of physics, necessitating further research in physical reasoning.
- Facebook AI Research developed PHYRE, a benchmark to evaluate AI's physical reasoning capabilities through physics puzzles.
- PHYRE aims to foster the creation of efficient learning algorithms that can generalise across various problem scenarios.
 The machines of the modern world can now be taught how to learn, adapt and improvise with great tact. Asking a robot to run, do a cartwheel or throw a pitch would have sounded like a chapter from a generic sci-fi novel a few years ago. But now with the advancements in hardware acceleration and the optimisation of machine learning algorithms, techniques like Reinforcement Learning are being put into practical use.
Hard coding a robot to perform even mundane skills poorly will take a lot of computational heavy lifting. However, it takes some ingenious constraint assumption to make the robot perform decently when put under unstructured, real-world situations.
Understanding of physics among current AI systems is still limited. The study of physical understanding and reasoning is still in its infancy and prior work has largely focused on specialised forms of physical understanding.
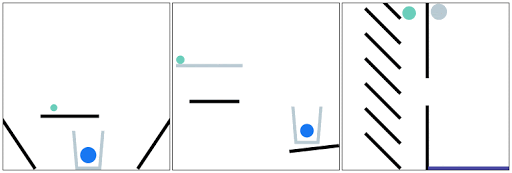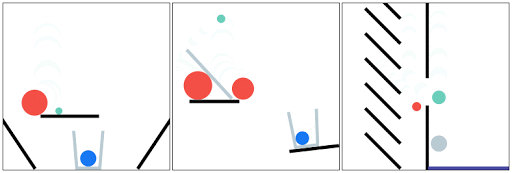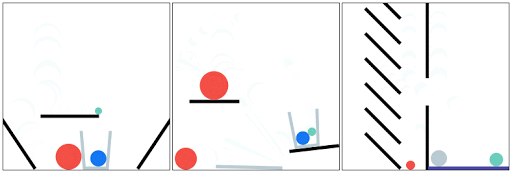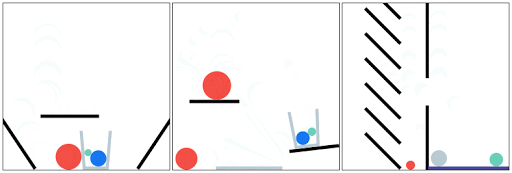
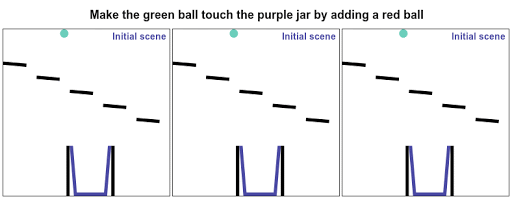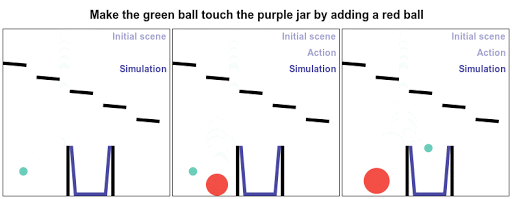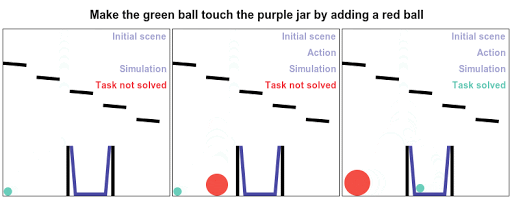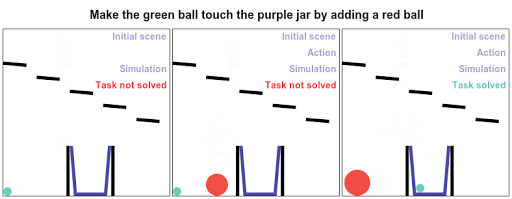
In an attempt to make AI more flexible, in the way it approaches the real physical world, researchers at Facebook AI Research, developed PHYRE. PHYRE is a new benchmark to assess an AI agent’s capacity for physical reasoning. Inspired by popular physics-puzzle games.
Reasoning With PHYRE
When Machines Learn To Reason
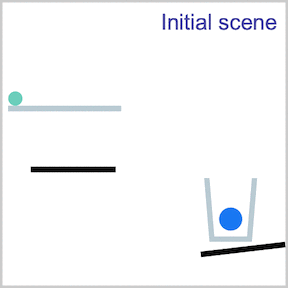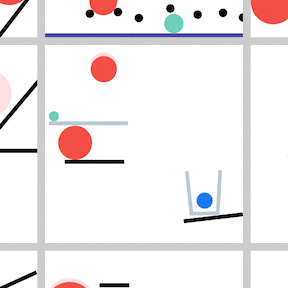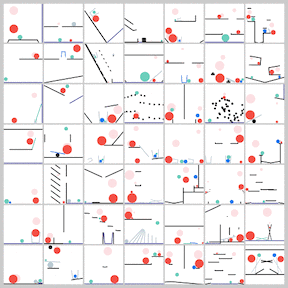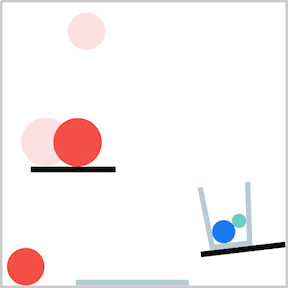 The number of potential actions that can be taken in PHYRE are large — tens of millions — compared with the hundreds in Go. And while AI breakthroughs in DoTA and StarCraft have relied on techniques requiring millions or even billions of trials to find a solution, PHYRE players can maximise their rewards only if they solve puzzles in as few attempts as possible.
In another curious case of excelling reinforcement learning in a physical environment, AI researchers from Google, Columbia University and MIT taught a new skill to the robots by making them toss things into baskets. THe TossingBot could pick things of different shapes and sizes and gently throw them into a target location like fruit into a basket or a banana peel into a trashcan.
The joints of a robot can have only so many degrees of freedom. And, to achieve skills like tossing, the synergies between grasping and throwing have to be figured out.
To do this, the researchers used a physical simulator, which is modelled on control parameters and then tried to improve the activity with the help of deep learning.
The researchers named this symbiosis of deep learning and physical reasoning as Residual Physics. As the name suggests, the bot, if trained using the laws of projectile ballistics, it can then be leveraged to learn an estimation of the target area or by how much it is missing the target. Minimising the miss is where deep learning comes in.
Future Direction
This integration of physics with deep learning enables faster learning in changing environments. The efficient the systems the better because in the real world, systems can’t be expected to make millions of mistakes before arriving at the correct action. Experiments such as above indicate that a machine can learn object-level semantics from its interactions with the physical world; in other words more human-like. This is another huge leap towards the realisation of artificial general intelligence.Spotted an error? Tell our editors. Read our editorial standards and corrections.