5 min
 MachineHack concluded its 15th successful competition by announcing winners for its recent hackathon Predicting The Costs Of Used Cars. This hackathon, sponsored by Imarticus Learning, was launched in June and received active participation from over 1,700 participants out of which 3 emerged as winners.
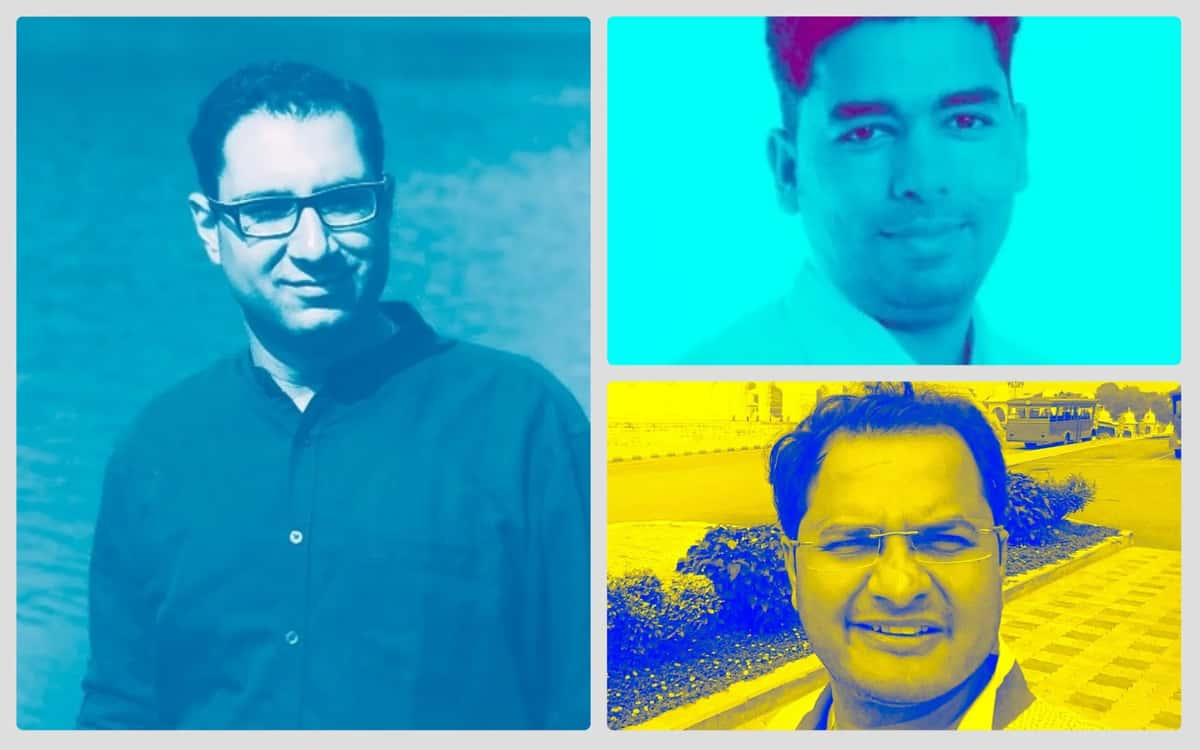
Participants Divyanshu Suri, Sandeep Rathod and Vasim Shaikh won the first, second and third places respectively on the hackathon leaderboard.
#1: Divyanshu Suri
Now a Senior Manager of Machine Learning at AXA XL, Divyanshu Suri is not new to MachineHack. Last year he had won the How To Choose The Perfect Beer Hackathon and still remains on the very top of the leaderboard. Having done his Bachelors in Statistics from Delhi University and a Masters in Applied Statistics from IIT Bombay, Divyanshu was amazed by the real power of data science in his second job at EXL Service where he worked in insurance analytics. He then went on to participate in many online hackathons gaining knowledge and improving his skills. Now, as a Senior Manager, he applies predictive analytics to solve a variety of data science problems in commercial and speciality lines.Divyanshu’s Approach To Solving The Problem
He started by trying to demystify the data by performing exploratory analysis. He figured out the missing values and cleaned the unstructured data. He explained his process as follows: Following variables were converted to numeric by appropriately applying the units –- Mileage
- Engine
- Power
- New_Price
- Location
- Fuel_Type
- Transmission
- Owner_Type
- Mileage
- Engine
- Power
- Seats
- Company Name (like Honda, Maruti, Hyundai, etc)
- Car Name (Amaze, Alto, Innova, Jazz, etc)
- Name
- Power (after grouping it in bins)
- Engine (after grouping it in bins)
- Company Name
#2: Sandeep Rathod
Sandeep was Introduced to Data Science by his colleagues at Infosys and it became his passion in which he enjoyed the right blend of Mathematics and Analysis. Wanting to learn more and upskill in his newly found passion, he joined UpX academy which gave him the right tools and confidence to win hackathons. Sandeep is now a Project Manager at Infosys. Sandeep has come close to victory on other hackathons at MachineHack and he is familiar with the platform. He said “MachineHack use cases are a good encouragement for naïve people like me. I would like to thank them for proving such a platform to compete and learn machine learning.” Approach to solving the problem: Sandeep’s approach to the problem was straight forward. He provided more focus on imputing the missing values and feature generation. He had his focus on one particular feature ‘New_Price’ which had a huge ratio of missing values in the dataset. He imputed the missing values by comparing the Brand, Model and Price of same cars. He spent most of his time in cleaning the data as he believed clean data would provide more accurate results, which totally paid off. Click here to view the code.#3: Vasim Shaikh
Having completed his Masters in Finance and with a zero background in Computer Programming, Vasim’s passion for Data Science began out of curiosity. He had worked with numbers and that being the only factor that connects him to data, he enjoyed playing around with it, generating insights, explaining complex patterns through visualizations and predicting numbers. His curiosity urged him to learn more from all available resources like MOOCs and books. Vasim is now an expert in analysing, exploring and wrangling tabular data.His skills with data and numbers have taken him to the Manager Of Data Strategy & Analytics position at Willis Tower Watson. Like the other two winners, Vasim is also a regular user at MachineHack having participated in multiple Hackathons.On being asked of his experience at MachineHack he responded “It is an amazing platform, where budding data scientist can showcase their skills and develop and learn new techniques” Approach to solving the problem: Vasim started with feature generation extracting as much information as possible from the given set of data. Given below are the steps of his approach as explained by him. Pre-Processing steps:- Extracted Manufacturer and Brands from Name.
- Extract variants, whatever I could
- Convert year to Age of the car
- Clean Engine, Mileage and Power variables
- Log transformation to Engine and Power, this increases the correlation
- Impute mean values for Engine missing values
- Linear regression prediction used for imputing Power (Engine was used as X variable)
- Used divisible for different variables. E.g. Engine / Power, KM_driven / Age, etc
- Data split was stratified on variables Fuel Type, Transmission and Seats
- Used 25 baggings of XGBoost, hyperparameters derived from 5-fold cross-validation
- From Humanoid Robots to Telecom Trials, 12 Major Announcements at NVIDIA GTC Berlin 2026
- Anyone Can Make a Robot Move, Few Can Make It Stop
- After ISRO’s PSLV Failure, TakeMe2Space Looks to SpaceX for Reliable Launch
- Why AI Agents are the Next Frontier in Quantum Security
- Physical AI Squeezes Labour Market, And Low-Skilled Immigrant Jobs May Be First to Fall
- Rocket Math Isn’t Mathing: Why India’s Space Launches are Expensive