5 min
- Is the maintenance of fidelity of the gradient computations and weight updates during back-propagation.
- When weights, errors and gradients used in matrix multiplication are reduced to 8 bits, deep neural networks take a hit and there is a significant degradation in its final accuracy.
- Also, there is a noticeable impact on the convergence during network training.
- 32-bit weight updates, used in today’s systems, require an extra copy of the high-precision weights and gradients to be kept in memory, which is expensive.
How To Work Around An 8-bit FP
A new technique called chunk-based computations, when applied, allows operations like convolution to be computed using 8-bit multiplications and 16-bit additions instead of 16 and 32 bits, respectively. And, a floating point stochastic rounding for the weight updating process. In chunk-based computations, the accumulated computations are broken up into chunks. These chunks consist of deep learning dot products. Researchers have tested this technique to train ResNet50 model. Many of these techniques have been tested using chips of size 14 nm. The results indicate that chunk-accumulation engines can be used along with reduced-precision dataflow engines without increasing hardware overheads. As a baseline, accumulation in FP-32 increases linearly with vector length. A typical FP-16 accumulation with the nearest rounding (i.e., ChunkSize=1) significantly suffers swamping errors (the accumulation stops when length ≥ 4096). This is where the chunk-based accumulation can be used to compensate for the errors, as the effective length of accumulation is reduced by chunk size to avoid swamping. The effectiveness of the stochastic rounding can be seen below; although there exists a slight deviation at large accumulation length due to the rounding error, stochastic rounding consistently follows the FP-32 result.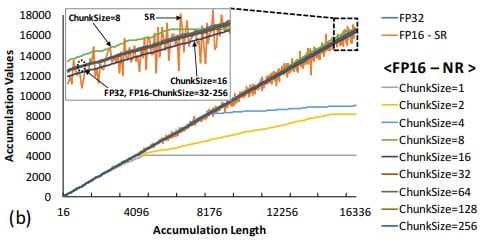 This success paves way for a new era of hardware training platforms which perform twice as well as the current systems.
This Paper Introduces:
- A new FP-8 floating point format that, in combination with DNN training insights, allows general matrix multiplication(GEMM) computations for Deep Learning to work without a loss in model accuracy.
- A new technique called chunk-based computations that when applied hierarchically allows all matrix and convolution operations to be computed using only 8-bit multiplications and 16-bit additions (instead of 16 and 32 bits respectively).
- An applied floating point stochastic rounding in the weight update process which allows these updates to happen with 16 bits of precision (instead of 32 bits).
- The wide applicability of the combined effects of these techniques across a suite of Deep Learning models and datasets – while fully preserving model accuracy.
- From Humanoid Robots to Telecom Trials, 12 Major Announcements at NVIDIA GTC Berlin 2026
- Anyone Can Make a Robot Move, Few Can Make It Stop
- After ISRO’s PSLV Failure, TakeMe2Space Looks to SpaceX for Reliable Launch
- Why AI Agents are the Next Frontier in Quantum Security
- Physical AI Squeezes Labour Market, And Low-Skilled Immigrant Jobs May Be First to Fall
- Rocket Math Isn’t Mathing: Why India’s Space Launches are Expensive